Ai
OpenAI's Decisions API vs Jev and Clef: what the docs actually say
OpenAI's Decisions API is in public beta: gpt-6-luna, typed answers, $0.10 per million input tokens. How it compares with Jev and Clef, and what OpenAI has not published.
Writing on AI, engineering, and building software.
OpenAI's Decisions API is in public beta: gpt-6-luna, typed answers, $0.10 per million input tokens. How it compares with Jev and Clef, and what OpenAI has not published.
Cloudflare's Clef is an Apache-2.0 decision model with Jev's API. What the benchmarks really say, what the packaging gets wrong, and how to choose.
Jev is TypeSafe's first System One model: it returns typed decisions with calibrated probabilities instead of text. How it works, the three primitives, real cost and latency, and where it fails.
Six Grok Bots to leave running overnight: inbox triage, social publishing through SocialRobot's MCP connector, receipt collection, competitor monitoring, support drafts and a Monday numbers recap. Prompts, connectors, and where each one stops for approval.
The working recipe to auto-run your test suite after a Cursor agent file edit, plus test on save for your own saves: afterFileEdit vs postToolUse, the stdin payload, fail-open defaults, and monorepo and Claude Code variants.
Grok Bot is xAI's always-on agent with its own computer. Every plan that unlocks it (from $20 Cursor Pro), the macOS, Windows, Linux, iOS and Android builds, what the limits actually are, the official Telegram bot, and why Discord has no official one.
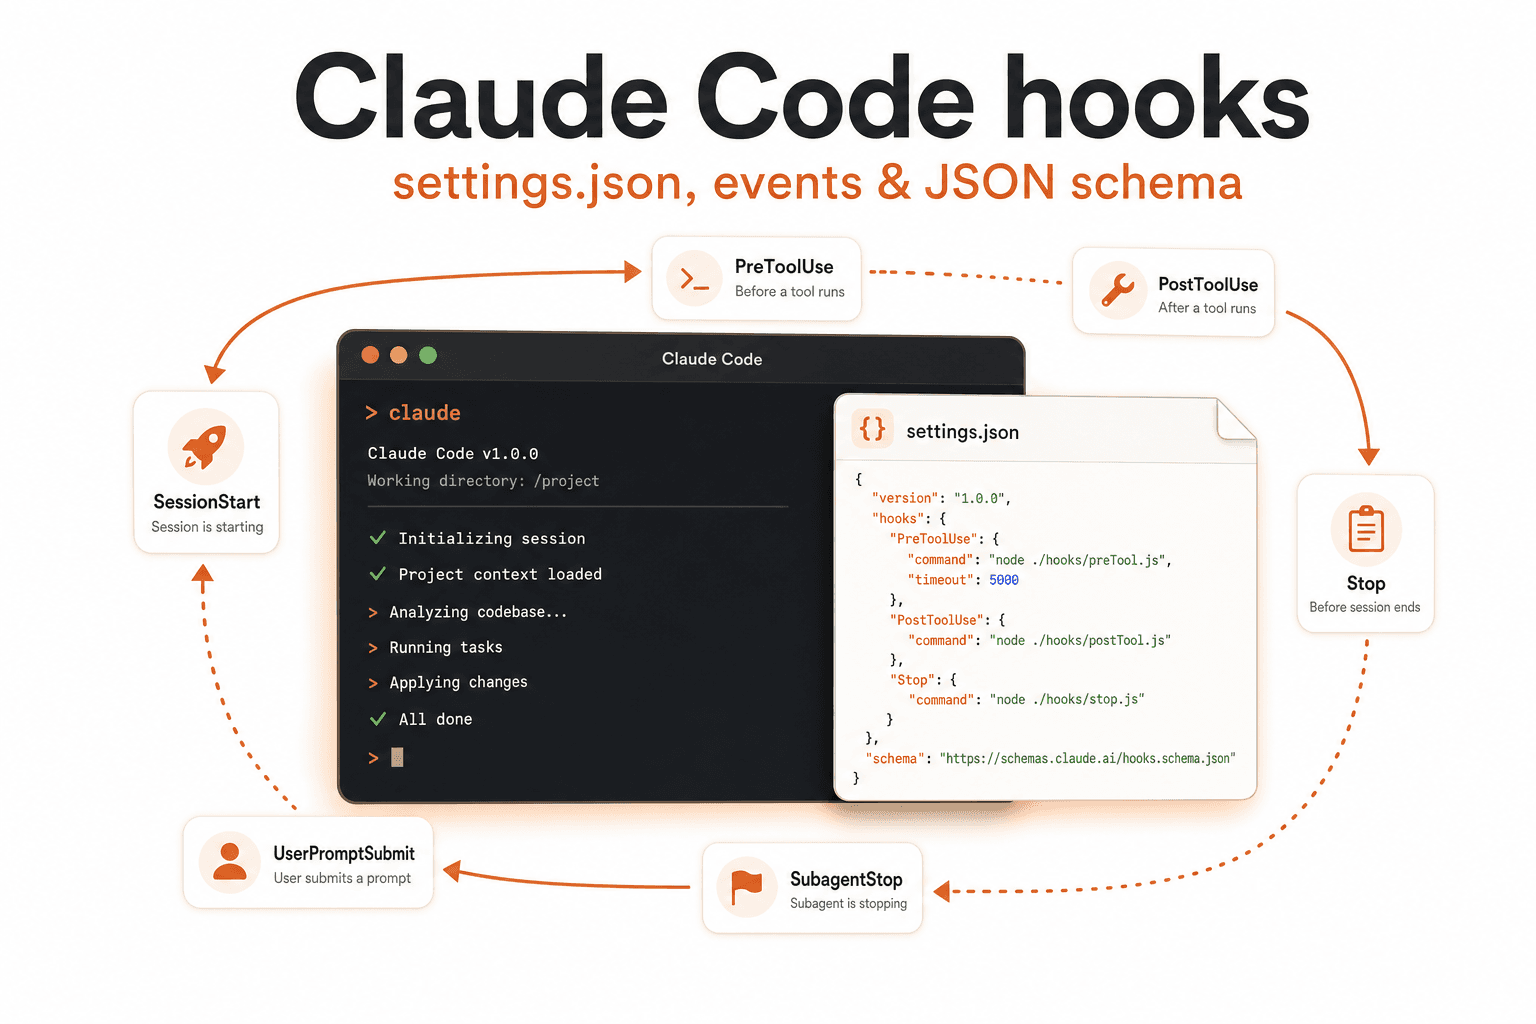
The complete Claude Code hooks reference: where hooks live in settings.json, every event, the JSON schema, permission decisions, exit codes, and copy-paste recipes.
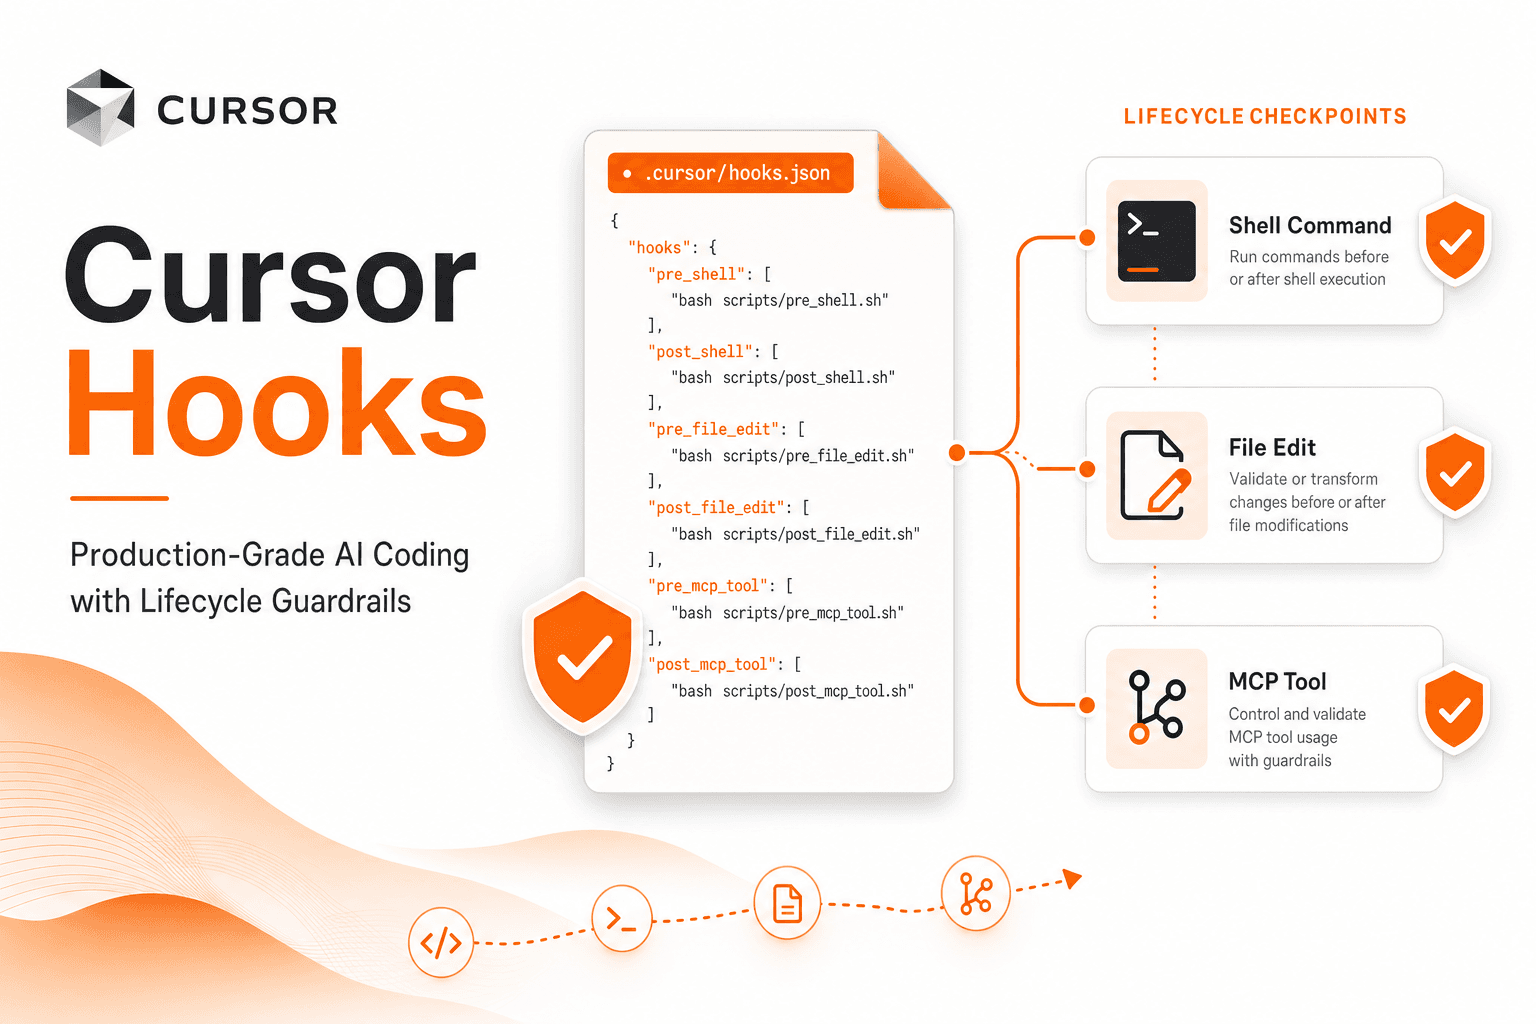
Every Cursor hooks.json event with its stdin JSON payload fields: afterFileEdit edits, exit codes, matchers, failClosed, and copy-paste recipes.
What are LLM evaluations, why they separate demos from production systems, and how to build them from unit tests to LLM-as-judge, with practical Braintrust code examples.
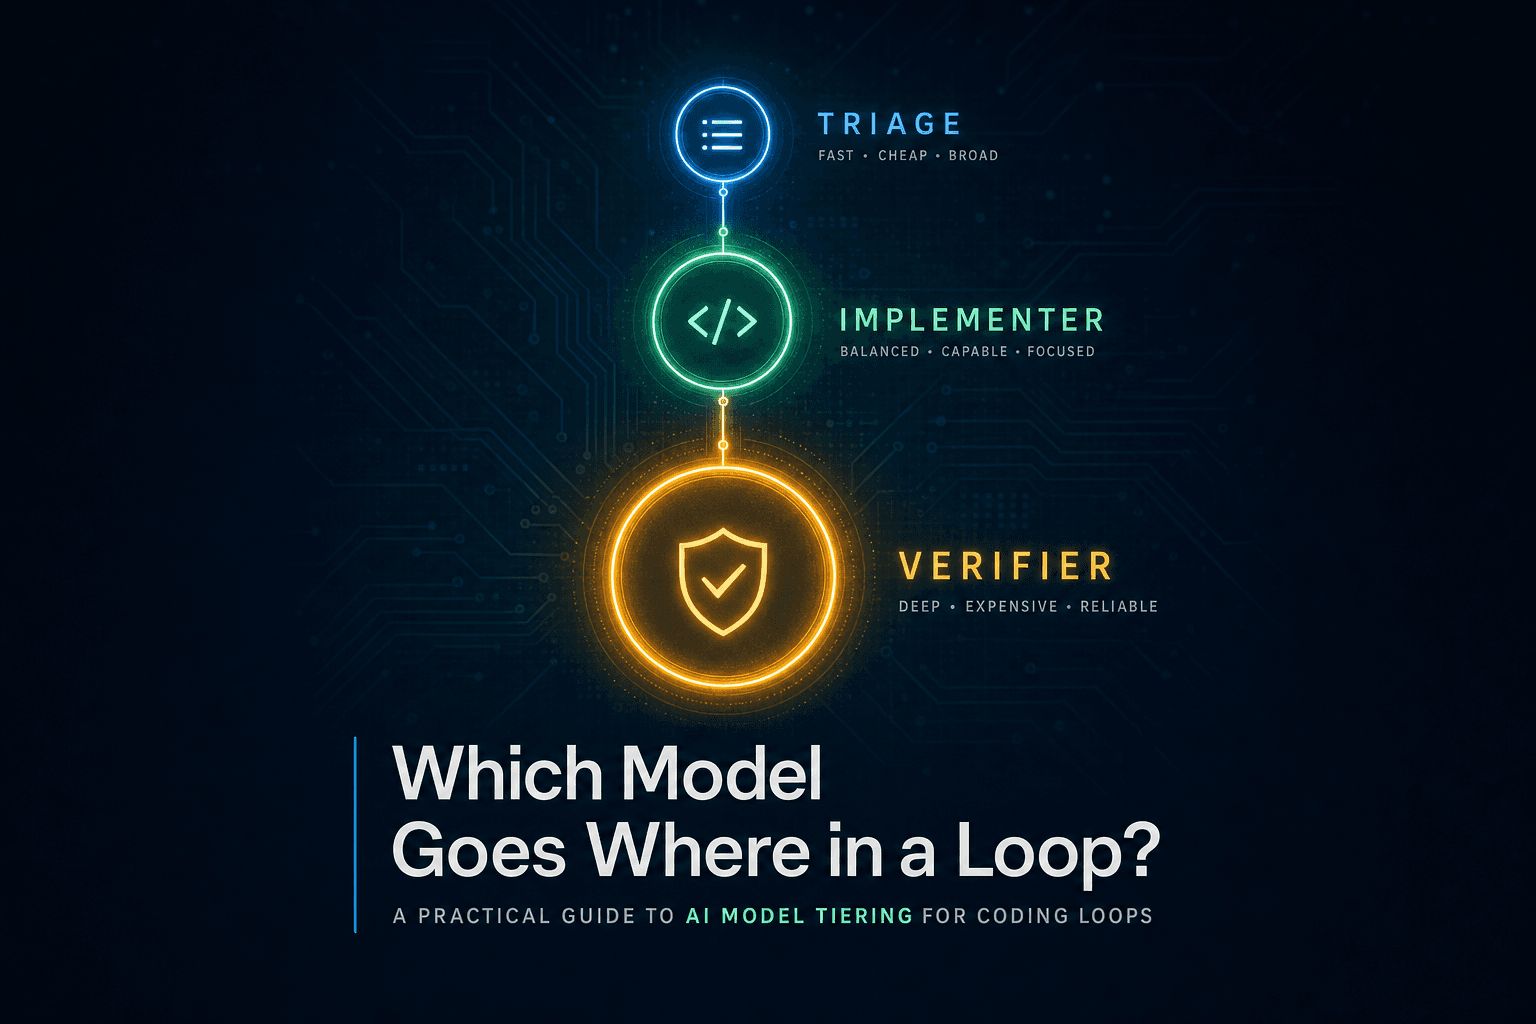
Running every loop role on a frontier model is expensive and unnecessary. Here's what the research says about tiering models per role, and what's still missing.
We rarely fail at work from one big blow. We fail from a hundred small permissions we grant until the environment is the problem and we're too tired to fix it.
Failure modes, token economics, and Souso-specific guardrails: what nobody tells you about unattended AI coding loops
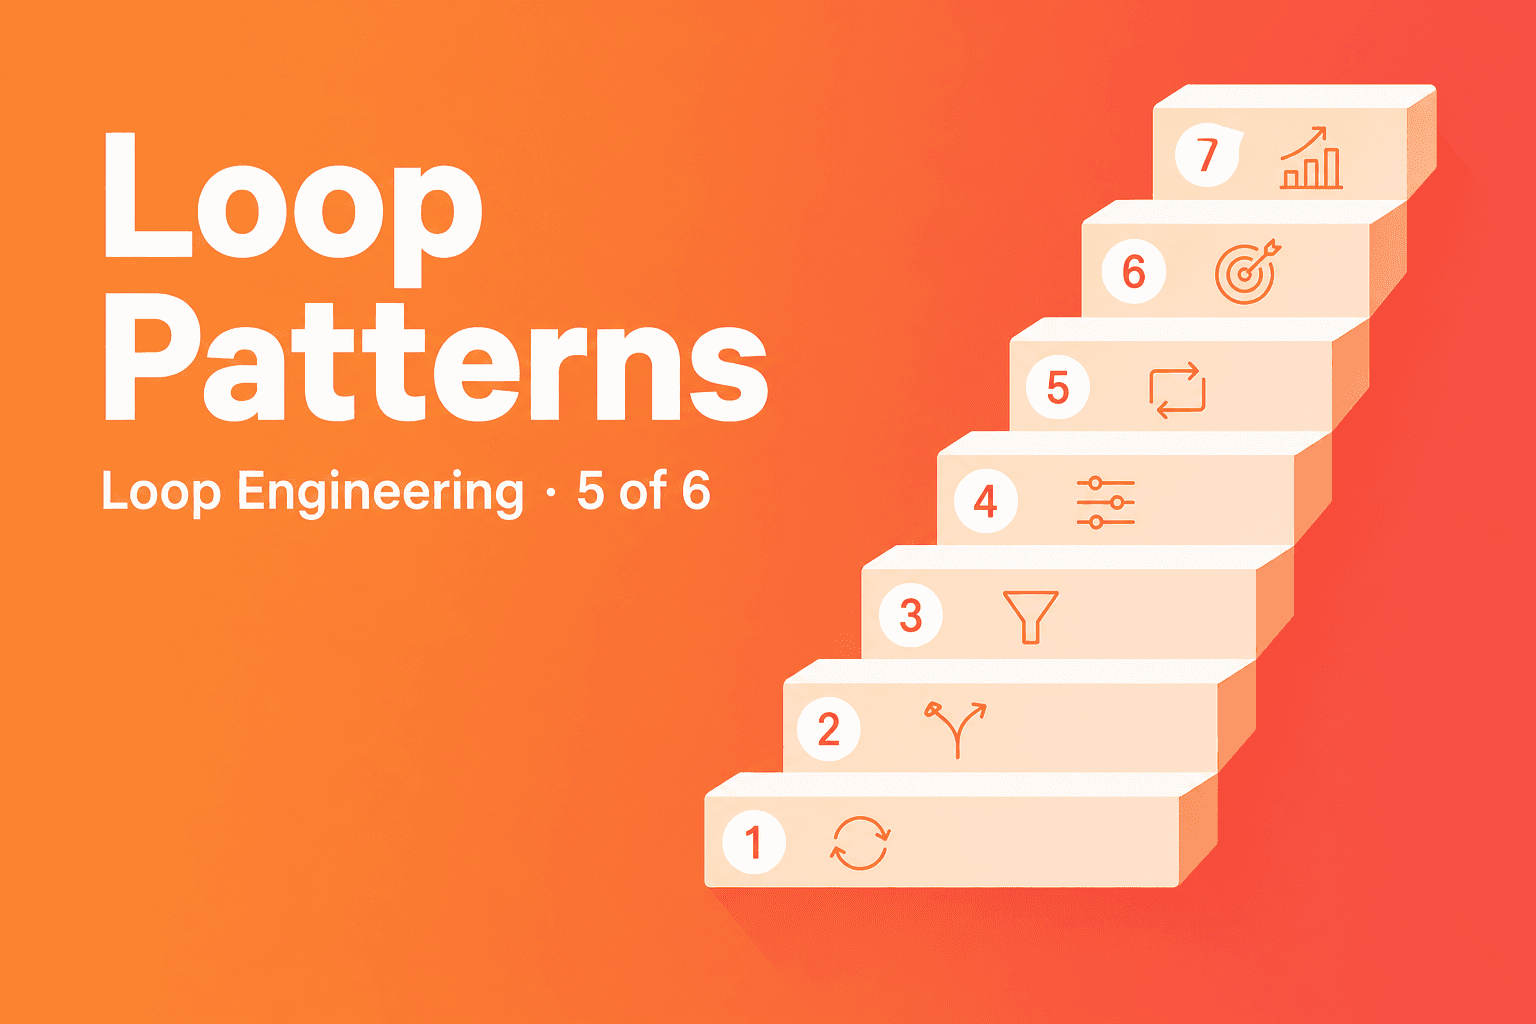
Seven production loop patterns with concrete Souso (smart-cart) scenarios, cadences, and risk levels
A step-by-step walkthrough of scaffolding and running Daily Triage L1 on Souso (smart-cart): report-only, zero risk
How GitHub Issues, CI, Slack, and Linear become loop input: the intake pipeline nobody explains
A deep dive into the six primitives that every unattended AI coding loop needs to function
How the shift from writing prompts to designing systems is redefining how we work with AI coding agents
Upgrading the version of your libraries can be scary. Lets make it easy
